DIY extract wrangles can be taylored to your data to identify and extract meaningful information from unstructured text. All custom extract wrangles (both diy and bespoke) can be found under the Extract tab of My Wrangles in the Data Wrangles task pane.
There are 2 types of DIY extract wrangle: Pattern Matching and AI. Read below to learn more about each.
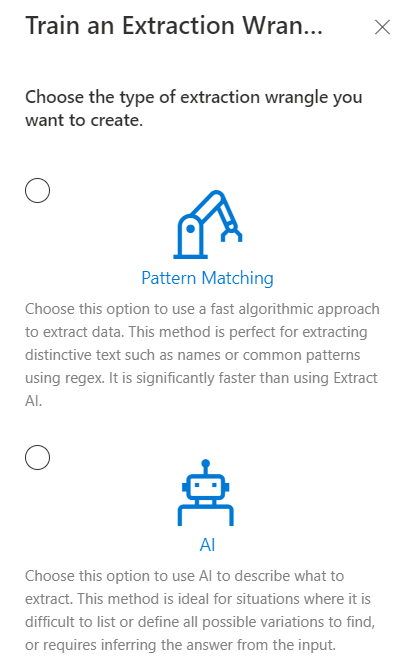
¶ Pattern Matching Extract Wrangles
Pattern matching extract wrangles return results that match the pattern(s) within the training data. These patterns can be words, sentences, numbers, symbols, any combination of the previous, or they can also be regular expressions as well. Read below to learn more about Pattern Matching Extract Wrangles.
It is important to note that (non-regex) pattern matching extracts match whole words that are separated by word boundaries. Word boundaries include anything that is not a letter, number or an underscore.
¶ Training Pattern Matching Extract Wrangles
To train an extract wrangle, first navigate to the extract tab (under the My Wrangles section of the Wrangles task pane) and click on the + icon. A new sheet (named Train-Extract) will open, this is where your training data will be stored.
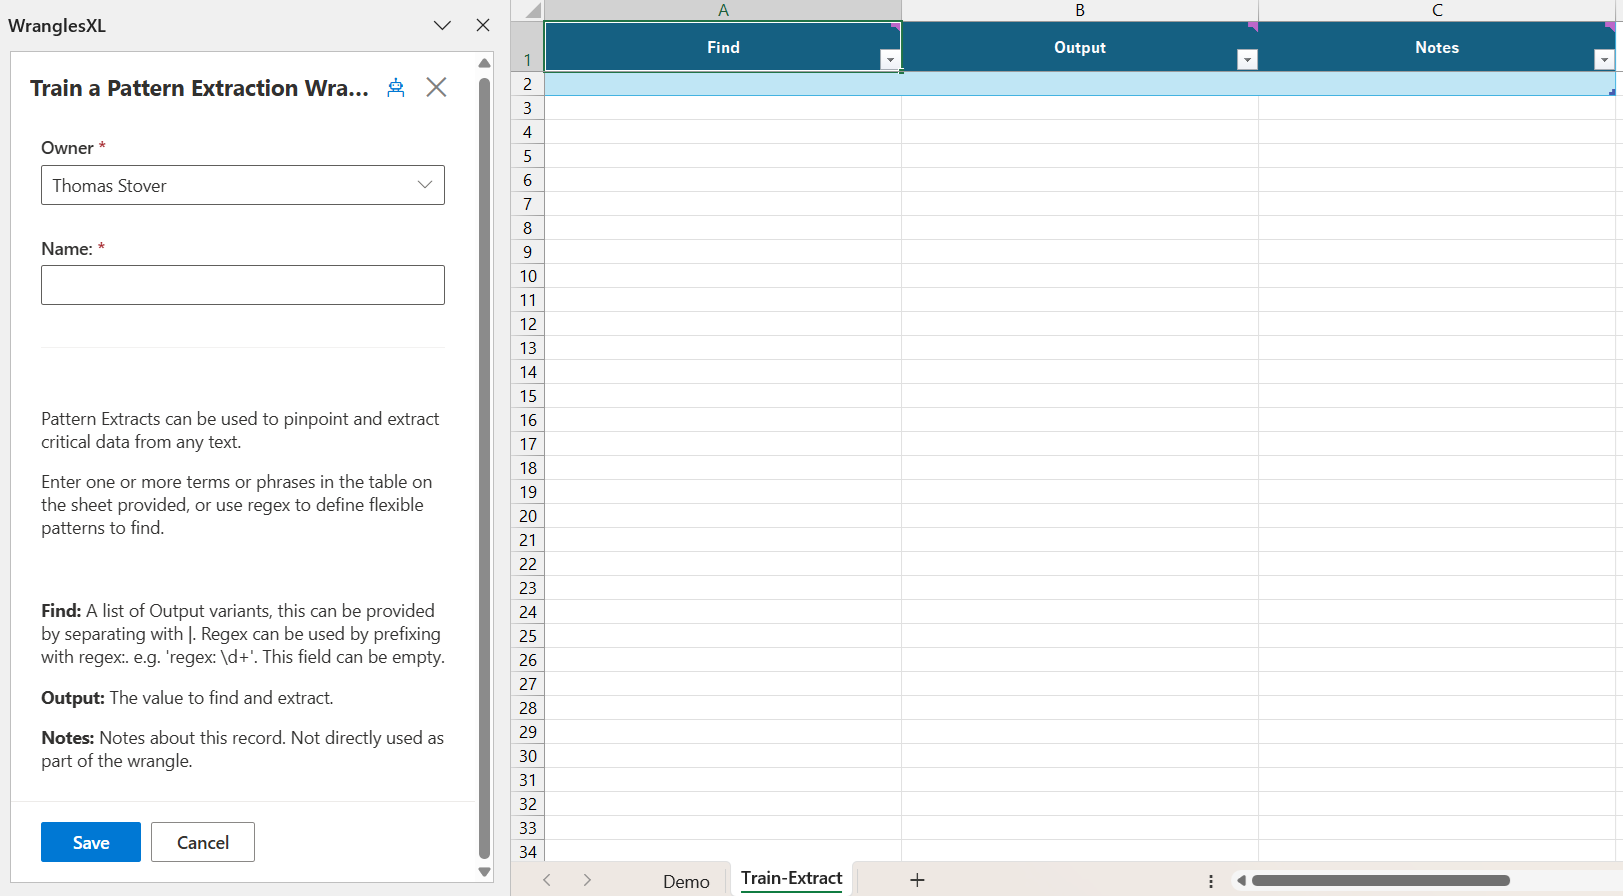
There are three columns that store training data, Find, Output (Optional), and Notes.
¶ Find
Search for this. A list can be provided by separating with |. Regex can also be used. e.g. 'regex: \d+'.
¶ Output (Optional)
If provided, this will be returned for anything identified from the Find column, instead of that value.
¶ Notes
Notes about this record. Not directly used as part of the wrangle.
Once your data is filled in, give your wrangle a name and click submit. Your wrangle will now appear in My Wrangles under the Extract tab.
¶ Updating Extract Wrangles
To update your extract wrangle, first click on the three dots next to the play button then click Edit.
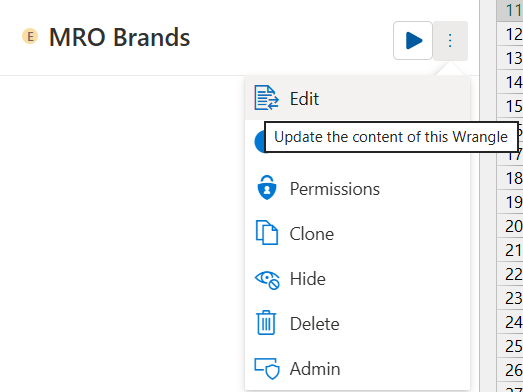
From here, simply update your wrangle as needed then click submit. Once your wrangle has been trained, it will be ready for use.
Note: When you retrain your wrangle, the training sheet is now named after the wrangle.
¶ Extracting Values Written in Multiple Variations
Extracting data when variations exist can be done in two ways:
¶ Multiple Rows
Write each variation on a separate row
| Find | Output (Optional) | Notes |
|---|---|---|
| MX | Mexico | |
| Mex | Mexico | |
| UK | United Kingdom | |
| GRB | United Kingdom |
¶ Same Row
Write each variation on the same row, separated by a bar (|)
| Find | Output (Optional) | Notes |
|---|---|---|
| MX | Mex | Mexico | |
| UK | GRB | United Kingdom |
¶ Negative Variants
Negative variants allow users to exclude variants which would otherwise be a match by leading them with a "-". When a negative variant is the only variant, or is the leading variant then it is important to us a "|" or a "'" (bar or single quote) in front of it so that Excel does not think it is a formula. "|-Acme Bearings" or "'-Acme Bearings for example.
| Find | Output (Optional) | Notes |
|---|---|---|
| '-Acme Bearings | Acme | Match Acme but not Acme Bearings |
| → |
|
¶ Extract using Regular Expression
For more advanced use, regular expressions (regex) can be used. To apply regex, prefix with regex:
Regex Cheat Sheet: A useful reference of regex terms.
Regex Testing: A useful tool to test regex
In order to implement regex into an extract wrangle, simply add "regex:" to the Find column before typing in your regex pattern.
¶ Samples
Extracting only the last name form a list of names.
| Find | Output (Optional) | Notes |
|---|---|---|
| regex: \s\w+ | Matches any word character (one or more times) that follows a space. |
| → |
|
¶ AI Extract Wrangles
AI Extract Wrangles are a premium feature that allow users to use text prompts to describe the type of content to extract from an input. Contact us by email or at this link to have Extract AI Wrangles enabled for your account.
There are some differences between AI Extract Wrangles and Pattern Matching Extract Wrangles that are worth mentioning. The biggest difference is that AI Extract Wrangles output a single column for each row in the "Find" column of the training data, as opposed to Pattern Matching Extract Wrangles which output all results to a single column. Another difference between the two is that AI Extract Wrangles can draw inferences from the input data. That is, the output does not necessarily have to be represented in the training data in any way.
¶ Training AI Extract Wrangles
Training AI Extract Wrangles requires the Find column. Optional columns include Description, Type, Default, Examples, Enum, Notes, Properties, Items, Required, Additional Properties, Nullable, Example - Input, and Example - Output. Legacy models with fewer columns remain supported.
Like other Wrangles, a new sheet will appear (entitled "Train-AI") when you create a new AI Extract Wrangle.
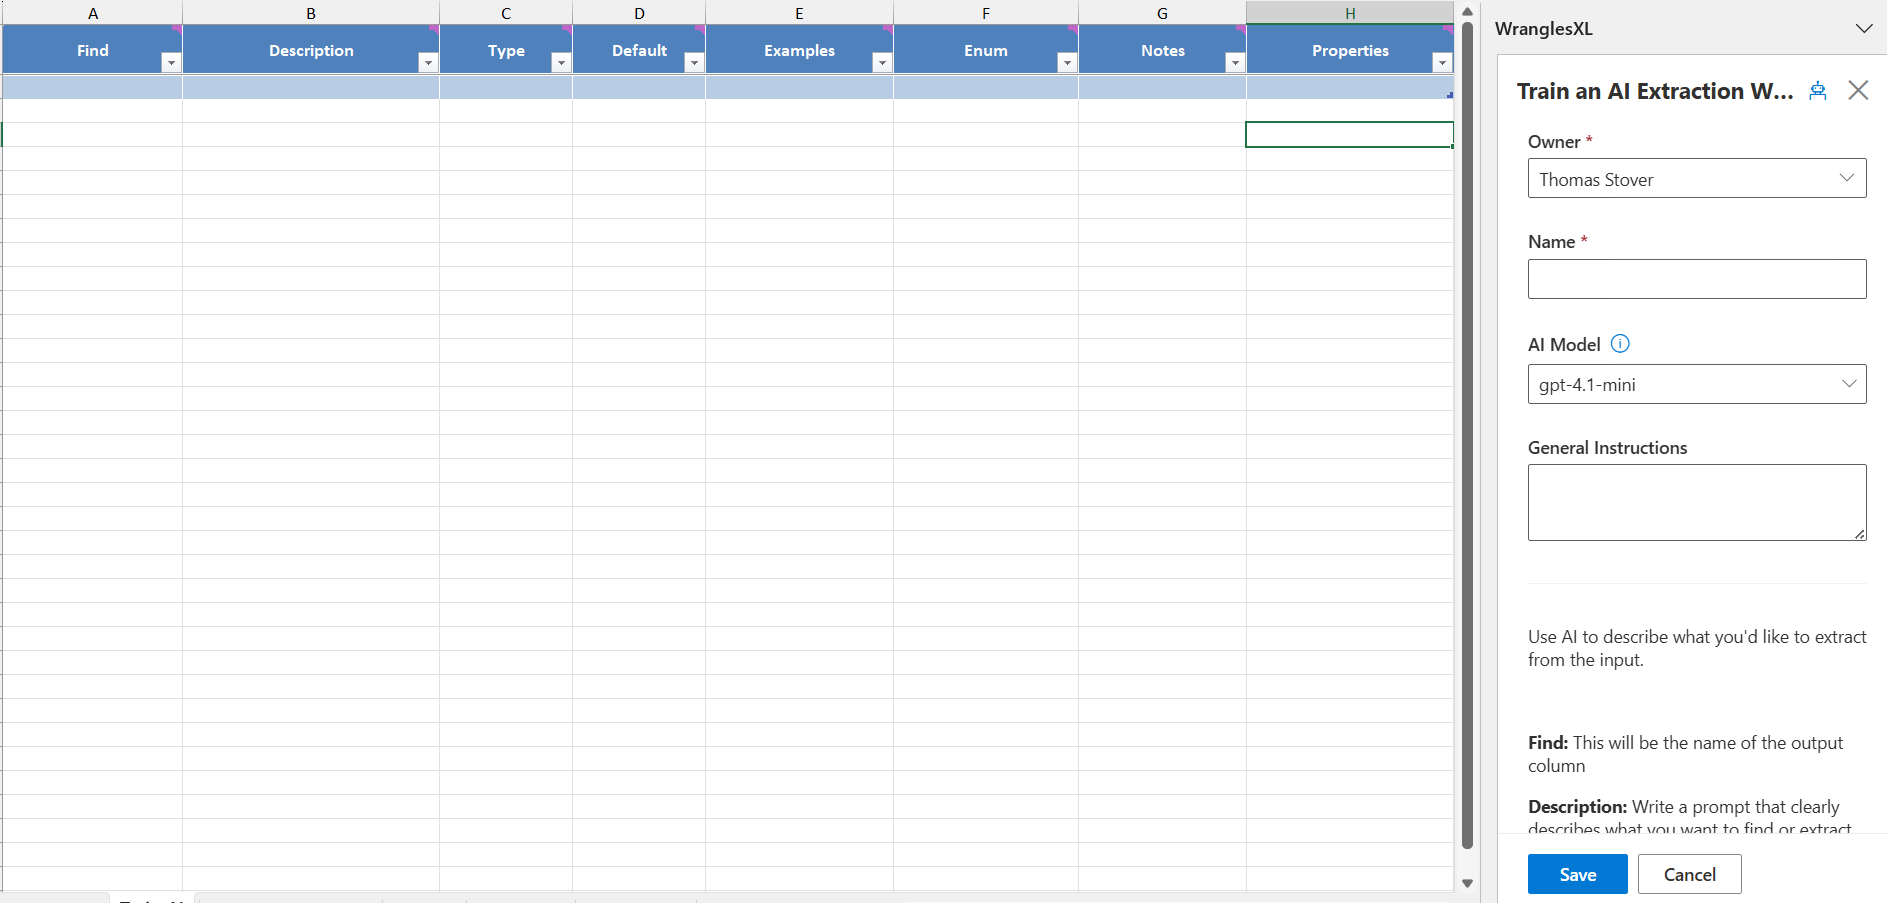
When training a new AI Extract wrangle (or also when editing), Owner, Name, AI Model, and General instructions can all be set.
¶ Owner
The user, team, or organization that will be given admin persmission for this wrangle. Only one can be selected, but more can be added in the permissions after the model is trained.
¶ Name
The name of the wrangle.
¶ AI Model
Extraction uses the model selected in the saved definition or current editor settings.
¶ General Instructions
General instructions for the ai. This can be thought of as a description of the task being performed, ie writing a description or extracting attributes.
Saved General Instructions apply to every attribute. Runtime recipe instructions append to the saved instructions. Attribute-specific rules belong in Description. Existing saved model choices remain in effect; upgrading the Python package does not automatically migrate a saved model to a different provider model. See AI Configuration for Python configured defaults.
¶ AI Training Columns
Only Find is universally required. Define the attributes and optional schema columns below. Default is a schema annotation, not a guaranteed replacement for missing evidence.
| Column | What to enter |
|---|---|
Find |
Required output attribute name |
Description |
Evidence, selection, inference, normalization, and conflict rules for this attribute |
Type |
string, number, integer, boolean, array, or object |
Default |
Optional annotated default value |
Examples |
Optional output-only examples |
Enum |
Allowed output values |
Notes |
Human notes; not sent to the model |
Properties |
Named child fields for an object |
Items |
Schema for one array element |
Required |
Required named object properties; blank means all named properties |
Additional Properties |
Whether an object accepts unknown keys; blank means FALSE when named properties exist |
Nullable |
TRUE or FALSE; blank uses the applicable default |
Example - Input |
Source text for one field-specific example |
Example - Output |
Expected value for the paired input |
Legacy saved models with fewer columns remain valid. Columns may be reordered,
and newer columns that this version of Excel does not recognize are preserved.
Find is the only required worksheet column.
¶ Easy cell formats
Excel values do not need to be strict JSON. Use the simplest unambiguous form:
| Need | Recommended entry | Also accepted |
|---|---|---|
| Simple list | Corded \| Battery |
Corded, Battery, [Corded, Battery], or strict JSON |
| Object value | {value: 120, uom: VAC} |
Strict JSON or a YAML-style block |
| Object properties | value: number \| uom: string |
value \| uom or a complete JSON/YAML schema |
| Array of strings | string in Items |
{type: string} |
| Array of objects | value: number \| uom: string \| material: string in Items |
A complete item schema |
| Boolean | An Excel TRUE or FALSE value |
The text true or false in Boolean/schema cells |
Prefer | for human-entered lists. Commas remain supported for compatibility,
but a comma may also be part of a value. Quote or bracket a value containing a
literal comma, such as ["500-3,100"].
The parser accepts JSON and a restricted, JSON-compatible form of YAML. It
rejects duplicate object keys, YAML tags, anchors, aliases, non-string object
keys, non-finite numbers, and excessively deep values. Words such as yes and
on, ISO-formatted dates, and identifiers such as 001 remain strings.
In an Enum cell, an unquoted null token means JSON null and therefore
requires a nullable field. Use ["null"] when the literal word is intended.
¶ Object and array defaults
- Output fields are nullable by default, but the output key is always returned.
- Named properties nested inside an object or array item are non-null by
default. Setnullable: truein a complete child schema when a nested value
genuinely may be null. - Blank
Requiredmeans every named property is required. - Blank
Additional PropertiesmeansFALSEwhen named properties exist. - An object without named properties is a dynamic dictionary. It uses
non-strict provider mode and local result validation.
These defaults make this sufficient for a normal value-and-unit object:
| Find | Type | Properties |
|---|---|---|
| Voltage | object | value: number \| uom: string |
It compiles as a closed object with both value and uom required and
non-null.
¶ Instructions and examples
Put attribute-specific rules in Description. Put rules that apply to every
attribute in General Instructions.
Good general instructions state evidence and conflict policy, for example:
Extract values supported by the input. Return null when information is absent.
When two numeric values differ only by rounding, use the more precise value.
Power source and AC/DC may be inferred from explicitly stated voltage when the
range is strongly characteristic; otherwise return null.
Use Examples for output-only guidance:
Corded | Battery
Use the paired columns when the source wording matters:
| Example - Input | Example - Output |
|---|---|
Rating 120V |
{value: 120, uom: VAC} |
Example - Output is required whenever Example - Input is populated. The
expected output is validated against the attribute schema before any model call.
Multiline input text remains text even when it contains lines such as
Description: Cordless drill; use braces only when the real input is a
structured object.
Object examples must include every non-null named property. For the Voltage
schema above, {value: 120} is incomplete because uom is non-null by default.
Supply {value: 120, uom: VAC}, or define uom with nullable: true in a
complete property schema if omission is genuinely valid.
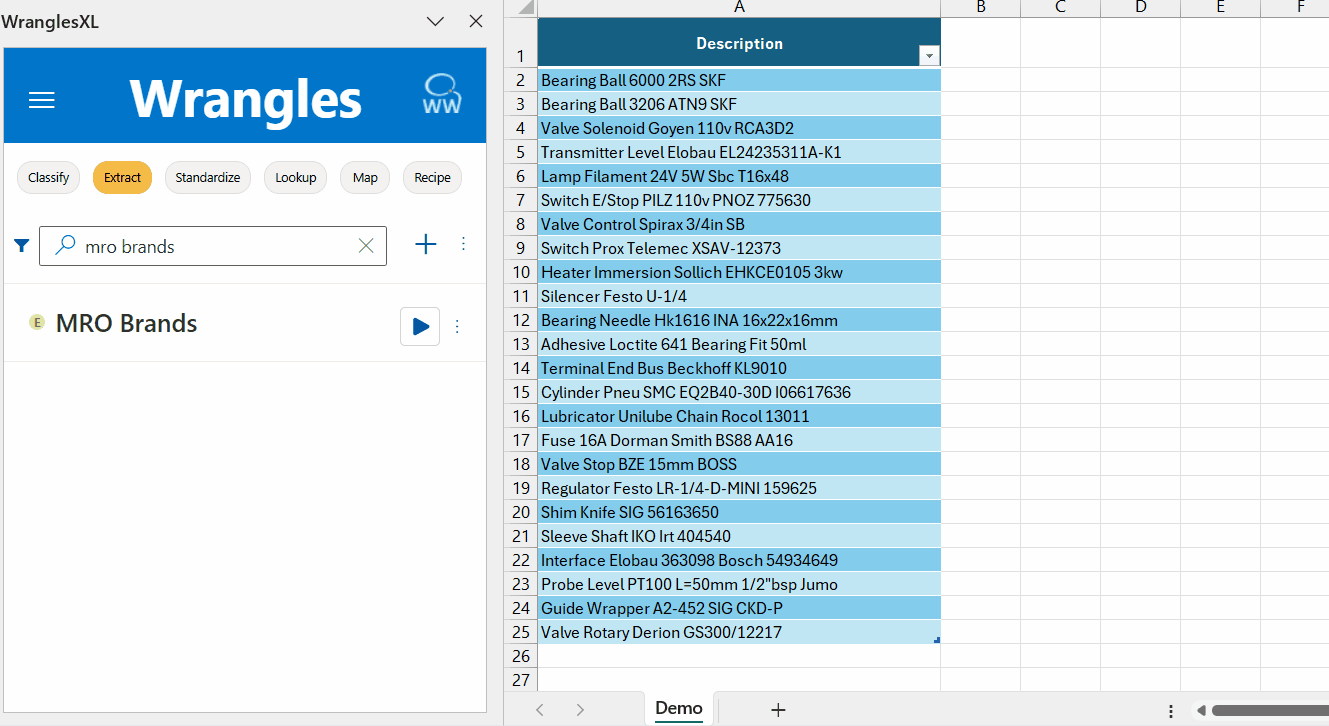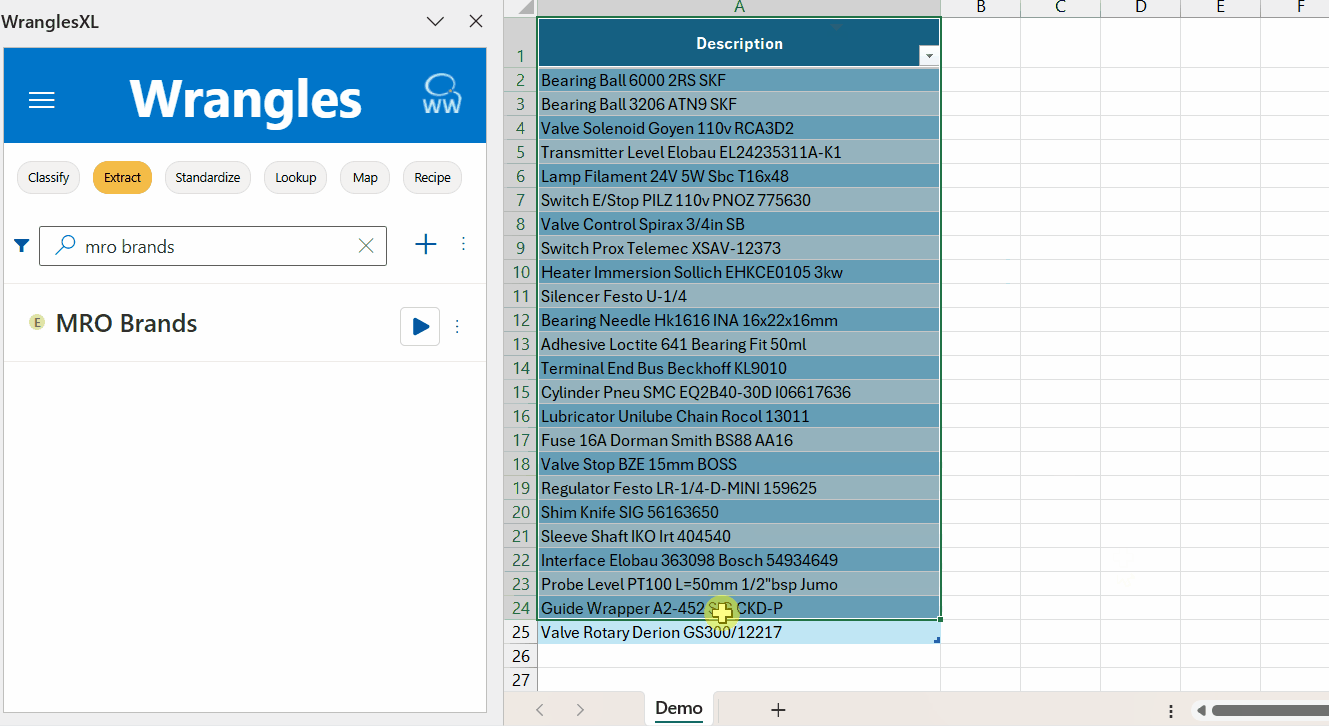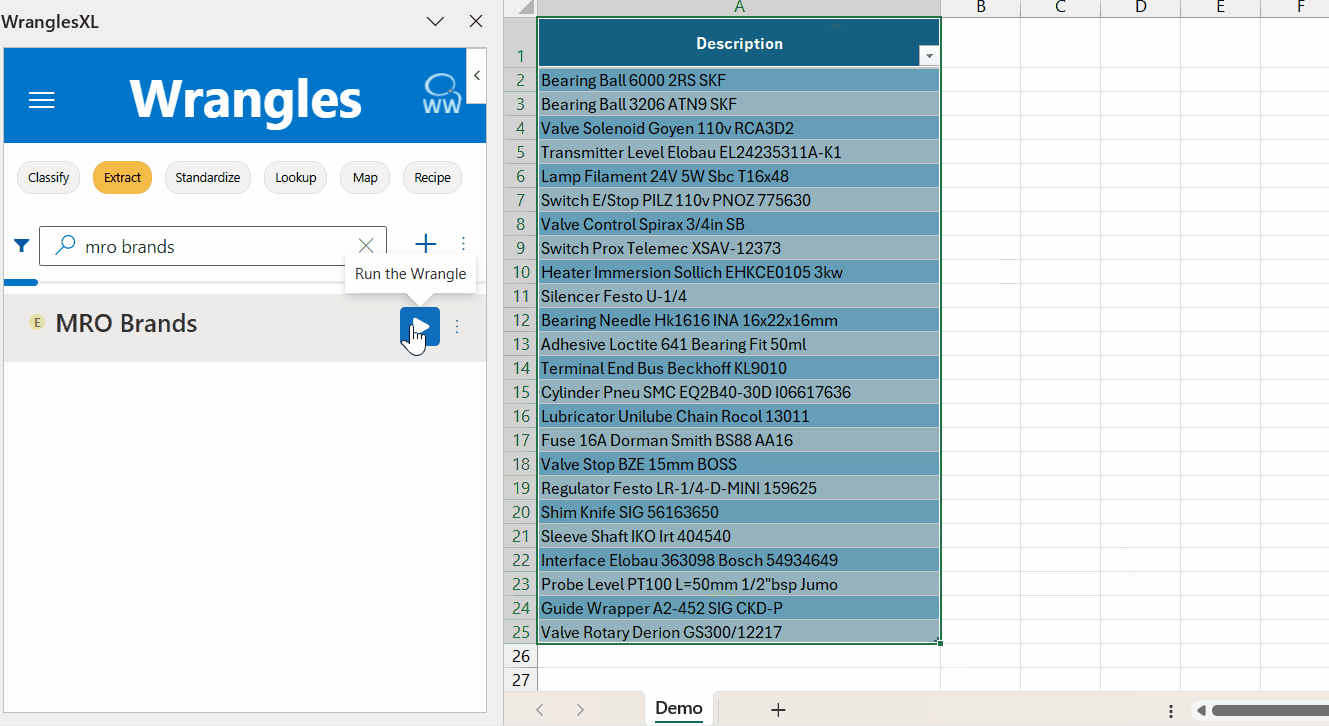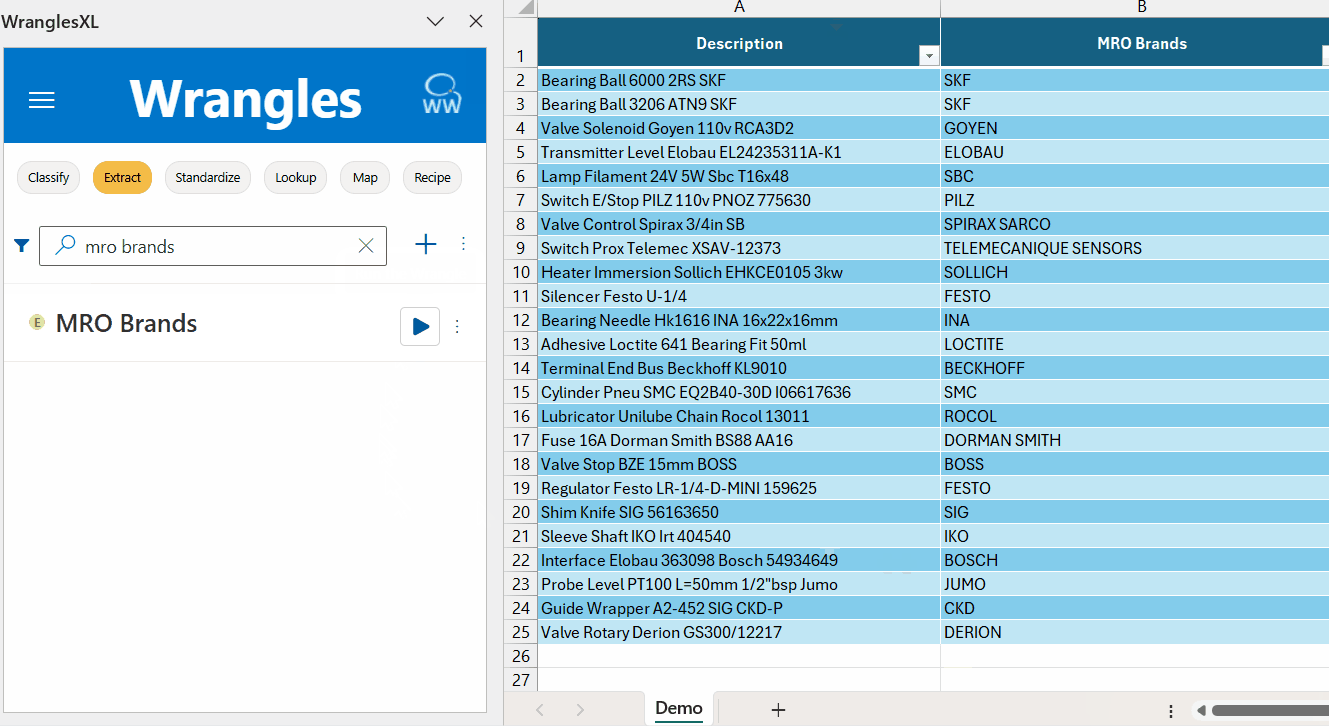
¶ MRO Brands Example
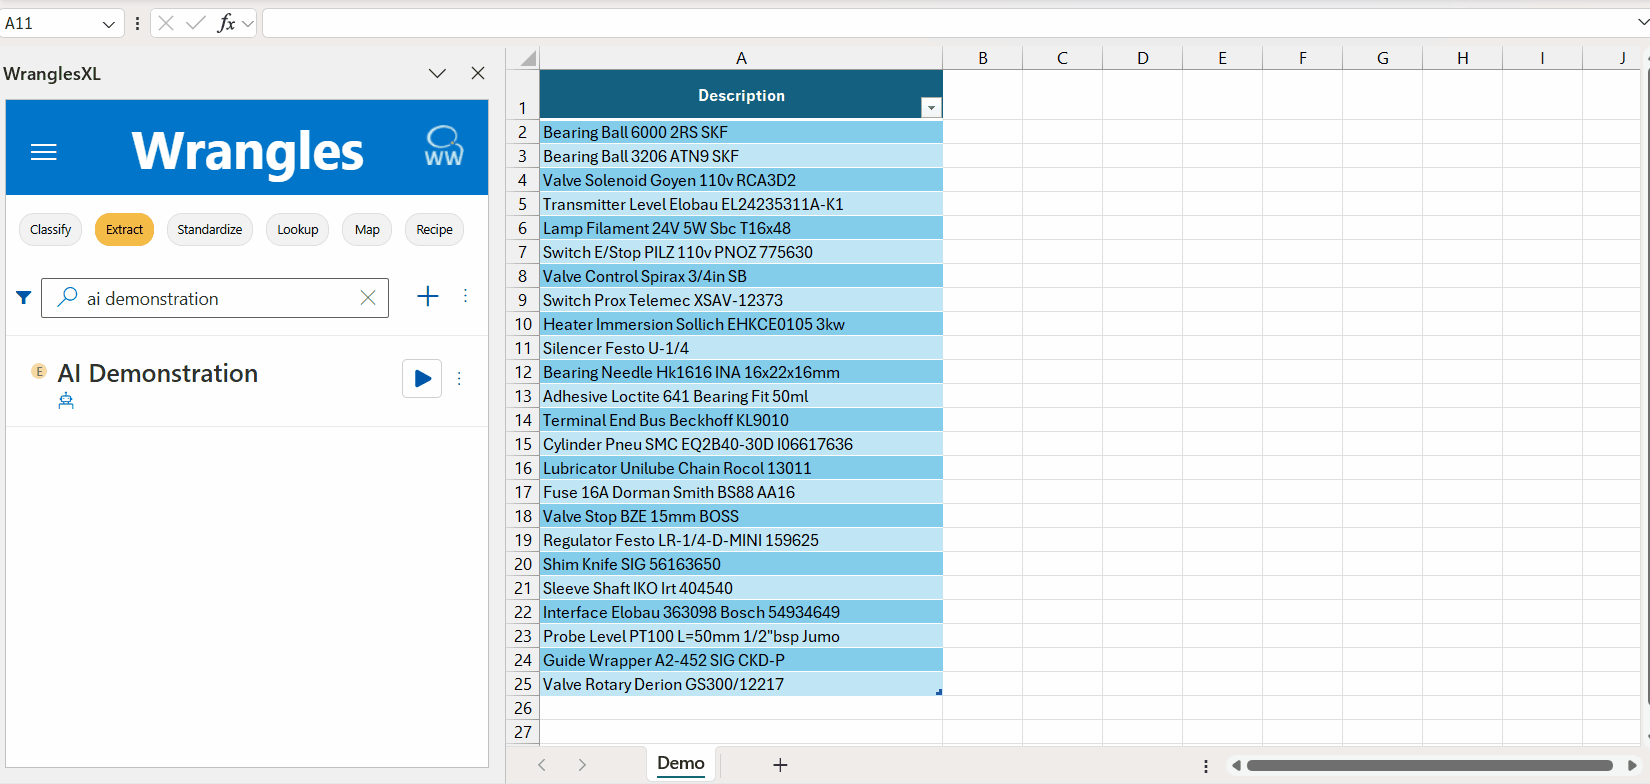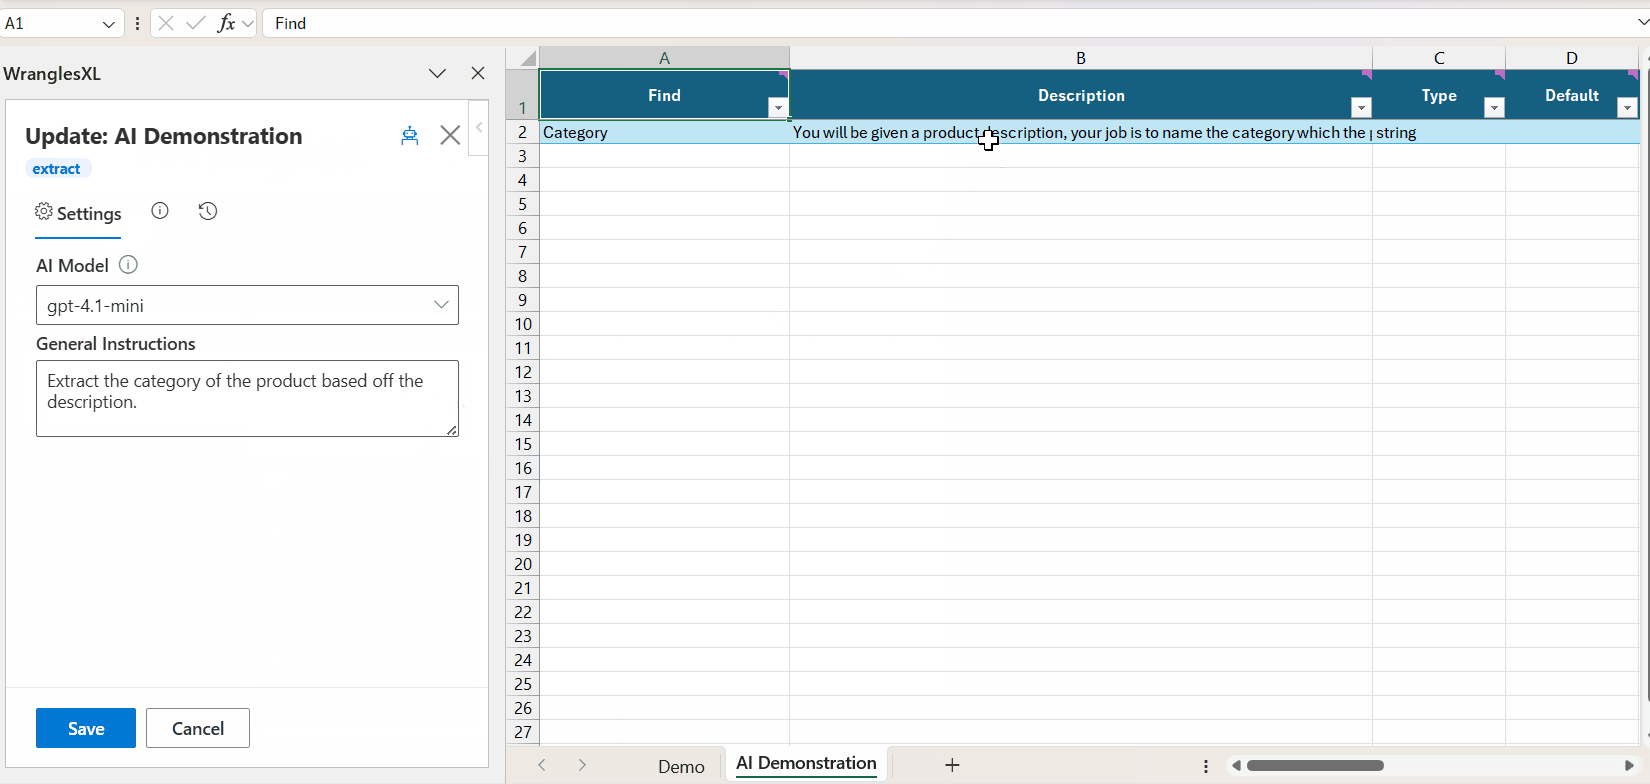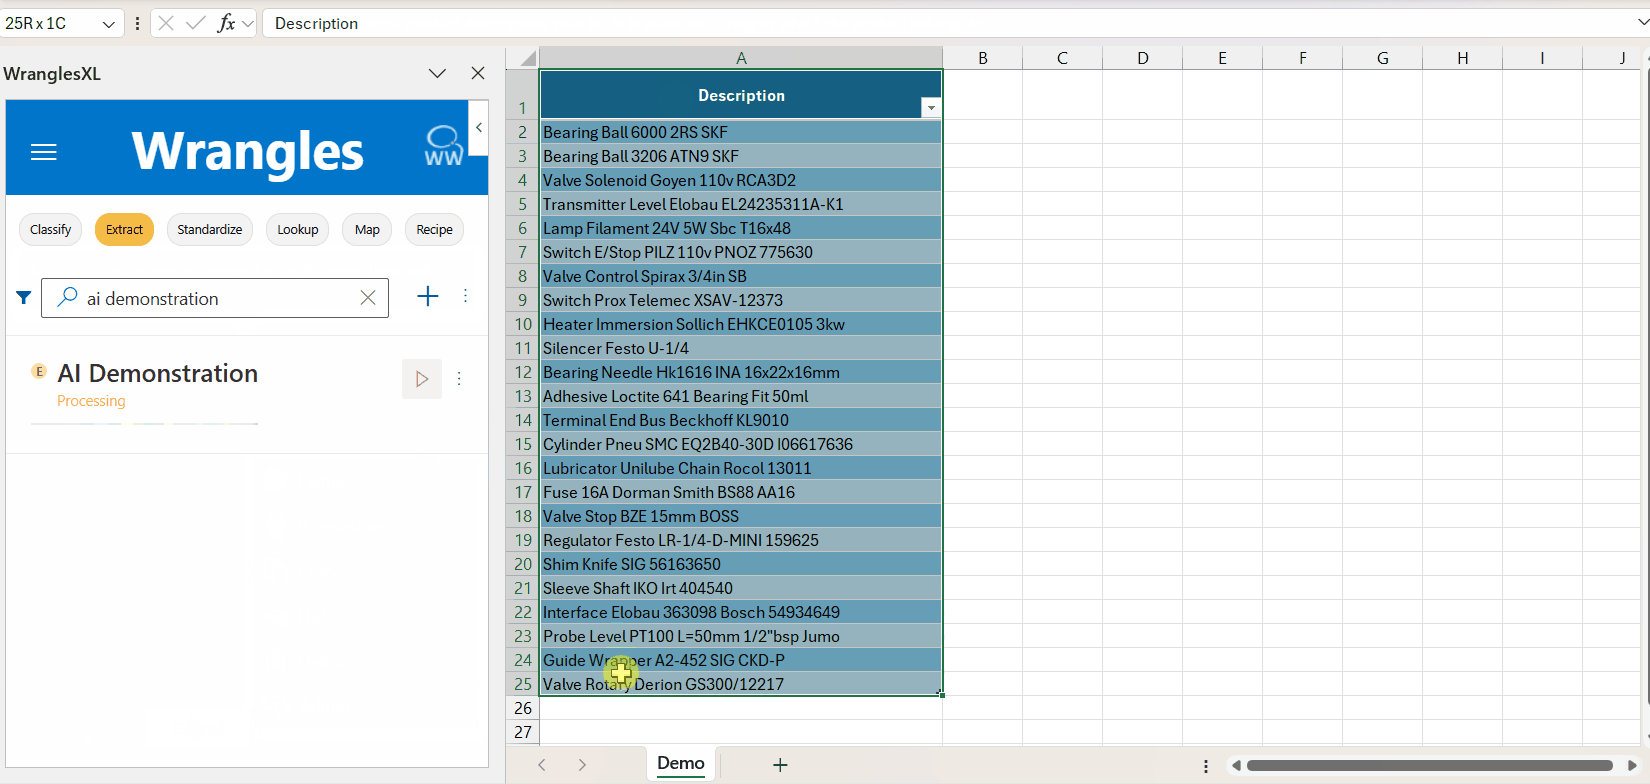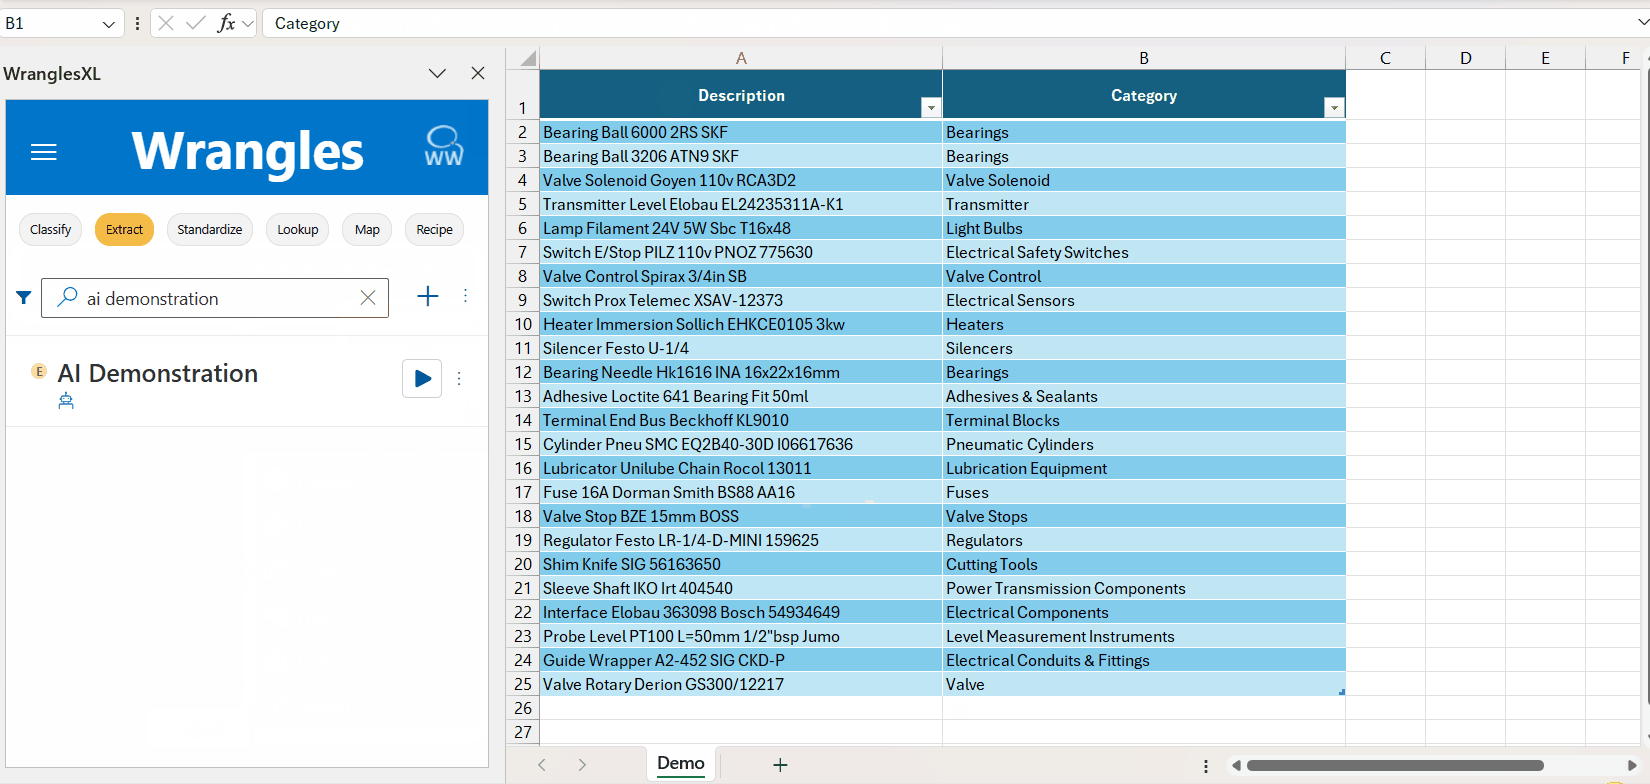
This is an example model for extracting brands in the MRO industry.
Brand names are an essential piece of product data. Supplier brand name data is especially important on an eCommerce site where customers want to search and filter by them. As with all product attributes, brand data can be inconsistent, often buried in a field with other data (e.g. a catch-all description field).
¶ Settings
Custom Extract Wrangles have settings that allow the user to taylor the output to their specific use case. Settings are found by clicking the gear (next to the New Wrangle button) on the extract tab. See below for a description of these settings.
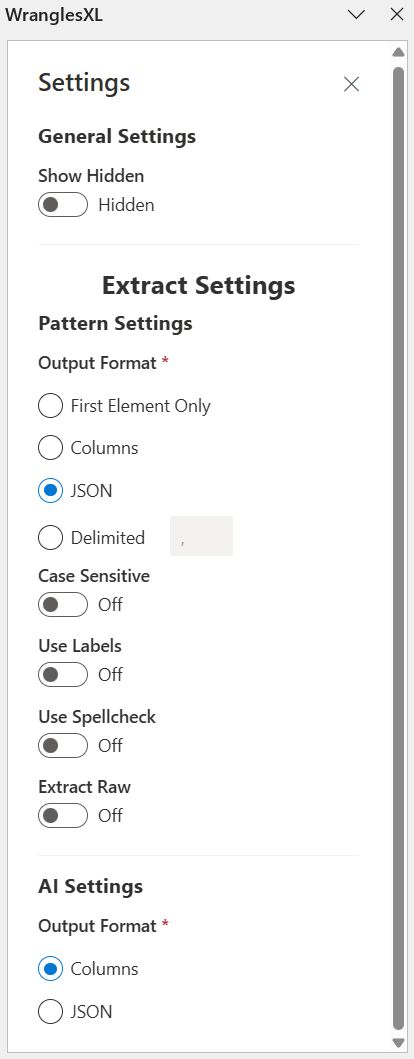
¶ General Settings
Settings that are applied accross all wrangles, not just extract wrangles.
¶ Show Hidden
A toggle to show wrangles that have been hidden by the user.
¶ Hide Stock Wrangles
A toggle that hides all stock wrangles from the My Wrangles list.
¶ Extract Settings
Settings that are specific to extract wrangles.
¶ Pattern Settings
Settings specific to pattern based extract wrangles.
¶ Output Format
This allows users to determine how the extract will output data. There are four different options; First Element Only, Columns, JSON, and Delimited.
¶ First Element Only
Return only the first result.
Note: This outputs matches it finds in the input based on the order they are listed in the training data.
¶ Columns
The Columns settings allows you to output multiple results from extract in individual columns rather than as a delimited string or JSON array. This will create as many columns as are needed for each result to end up in it's own column. Keep in mind, that some rows will have more matches than others, so there will likely be many empty cells when using this setting.
¶ JSON
Return the results as a JSON array e.g. ["result1", "result2", ...].
¶ Delimited
Return the results separated by a delimiter of your choice. e.g. with commas: result1, result2.
¶ Case Sensitive
Extract only values that match the Wrangle data case.
¶ Use Labels
Extract values in the format of an object → {category: value}.
If multiple "values" are found, the value will become an array:
Wrangle data must be in the form of category: value.
See here for a more in depth look at use_labels.
¶ Use Spellcheck
Use spellcheck to also find minor mispellings compared to the wrangle data.
¶ Extract Raw
The Extract Raw setting allows users to return the raw value of the match found. That is, it extracts matches without standardizing their output.
¶ AI Settings
¶ Output Format
Set how the output is formatted for AI Extracts
¶ Columns
Return the results into separated columns.
¶ JSON
Return the results as a JSON object e.g.
¶ Converting Your DIY Extract To New Format
As of 2025-9-22, the data for DIY Extract Wrangles requires a new format. Existing wrangles will continue to work as before with the old format until converted.
The new format is:
| Find | Output | Notes |
|---|---|---|
| BrandX | Brand_X | Brand X | |
| BrandY | Brand_Y | Brand Y |
Existing wrangles that use the old format will display a prompt to enable upgrading to the new format. This will convert the data in place, but will not be saved until it is submit.